
Use LOTX testing when you need proof that the physical transmission path works; use network testing and diagnostic tools when you need proof that services, traffic, routing, and applications behave correctly. Treating them as interchangeable is a common mistake. It wastes time, hides faults, and can make a clean network look broken when the real issue is a weak optical level, dirty connector, bad transceiver, or unstable line.
TLDR: LOTX testing checks the transmission layer first, especially optical power, signal quality, link stability, and transceiver behavior. Network diagnostic tools check packet flow, latency, routing, DNS, TCP behavior, and service availability. For example, a support team handling 120 branch outages per month may cut repeat tickets by 25% if it verifies LOTX results before running higher-layer troubleshooting. If the light level is wrong, no amount of ping tests will fix the link.
What LOTX Testing Actually Covers
In many telecom and infrastructure teams, LOTX testing is used as shorthand for Layer One Transmission testing or optical transmission validation. The exact meaning can vary by vendor or internal process, but the core idea is stable: LOTX verifies whether the physical transport medium can carry a signal within expected limits.
That usually includes checks such as:
- Optical transmit and receive power
- Insertion loss across fiber runs
- Return loss caused by reflection
- Transceiver health and compatibility
- Link stability over a defined test period
- Bit error rate on transport circuits
- Connector cleanliness and patch quality
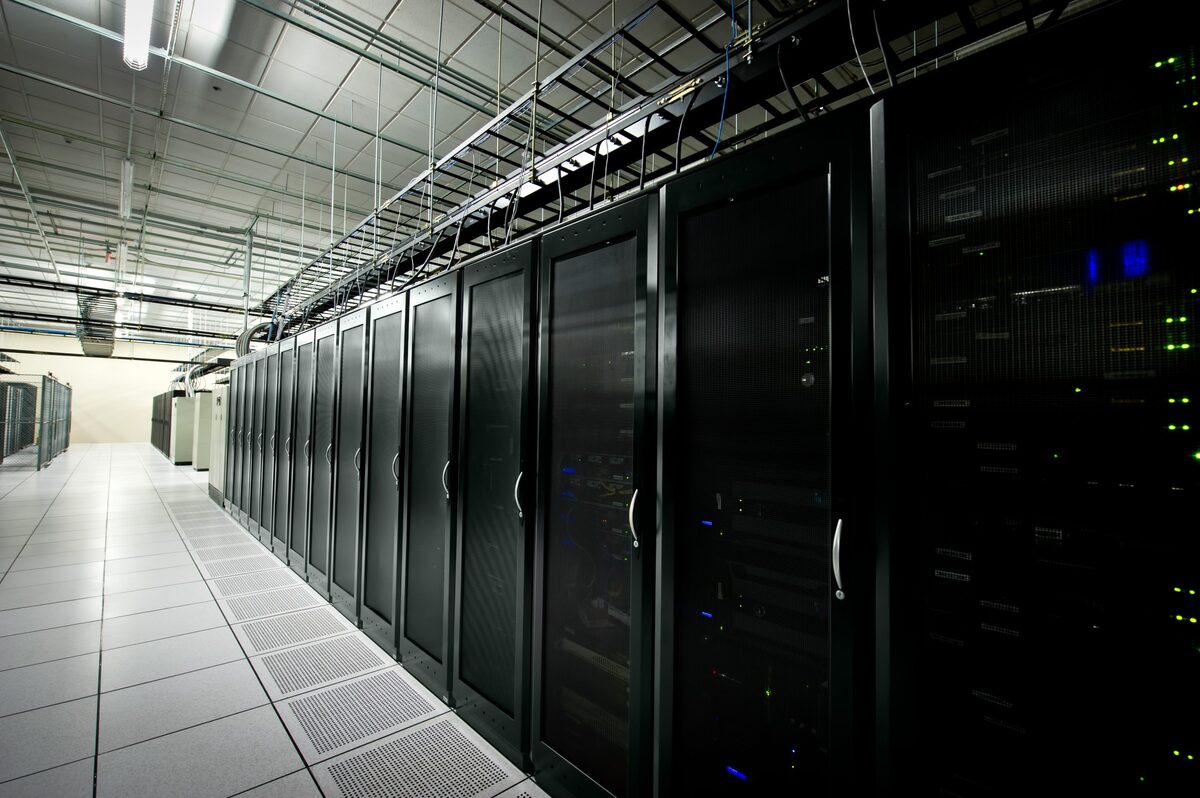
LOTX testing is not glamorous. It is also not optional. A dirty LC connector can create more chaos than a bad firewall rule. Honestly, it feels like too many teams still start with traceroute when they should start by checking light levels.
How Network Testing and Diagnostic Tools Differ
Network testing tools work higher in the stack. They focus on whether traffic can move from one point to another and whether services respond as expected. They help explain behavior after the physical path is healthy.
Common tools include:
- Ping for basic reachability and packet loss
- Traceroute for route path visibility
- SNMP polling for interface statistics
- Flow analysis such as NetFlow or IPFIX
- Packet capture with tools such as Wireshark
- Throughput testing with controlled traffic generators
- DNS and TCP tests for service troubleshooting
These tools answer questions such as: Is the route correct? Are packets dropping? Is the application slow? Is one site crossing a congested path? Is TCP retransmitting? Is the firewall blocking a port?
They are powerful. They are also easy to misuse. If a fiber span has marginal receive power, ping output may show packet loss, but it will not explain the root cause. You may see symptoms, not the fault.
LOTX vs Network Testing: The Practical Difference
The cleanest way to separate the two is by asking what layer is being trusted.
| Area | LOTX Testing | Network Diagnostic Tools |
|---|---|---|
| Main focus | Physical transmission path | Traffic, routes, services, protocols |
| Typical fault found | Bad optics, weak signal, fiber loss, dirty connector | Packet loss, routing errors, DNS failure, congestion |
| Best used | Before service activation or after physical changes | During live service troubleshooting |
| Evidence produced | Power levels, loss values, BER results | Latency, path, drops, retransmits, response codes |
The catch is simple: network tools depend on the physical layer being clean. If the transport layer is unstable, every higher-layer result becomes suspect.
A Realistic User Case Scenario
Consider a regional bank with 40 branches connected through fiber circuits. Users at eight branches report slow teller applications every morning between 9:00 and 9:30. The network team starts with ping and sees intermittent 3% packet loss. Traceroute shows no path change. Firewall logs look clean.
After two days, the carrier runs LOTX checks. One branch has receive power at -26.8 dBm, close to the transceiver threshold of -27 dBm. The connector is cleaned and reseated. Receive power improves to -19.4 dBm. Packet loss drops from 3% to below 0.1%, and teller transaction time falls from 11 seconds to 3 seconds.
That is the point. Network tools showed the pain. LOTX testing found the cause.
Image not found in postmeta
Where LOTX Testing Is Strong
LOTX testing is strongest before the network is blamed. It is especially useful during commissioning, cutovers, carrier handoffs, data center moves, dark fiber validation, and unexplained link flaps.
It gives teams hard numbers. Not guesses. A report may show that a fiber path has 2.1 dB loss when the design budget allows 3.0 dB. That is useful. It may also show 6.8 dB loss on the same path after a patch change. That result points directly at a physical issue.
LOTX also helps separate vendor responsibility. If an enterprise network team can show that optical levels are out of range at the demarcation point, the carrier has a clear fault to investigate. Without those numbers, expect to waste time on vague ticket updates like “monitoring shows no issue.”
Where Network Diagnostic Tools Are Better
LOTX testing will not tell you why BGP picked the wrong path. It will not show a bad DNS response. It will not decode a failed TLS session. It will not prove that a SaaS provider is rate limiting traffic.
For those problems, network diagnostic tools are the right choice. Packet capture can reveal retransmissions and resets. Flow data can show a backup job saturating a WAN link. Synthetic monitoring can show that users in one region see 420 ms response times while others see 80 ms.
Network tools are also better for continuous visibility. LOTX tests are often point-in-time or event-based. Network monitoring can run all day and raise alerts as conditions change.
Best Practice: Use Both, in the Right Order
A serious testing process should not pick one method and reject the other. It should order them correctly.
- Confirm the physical path. Check optics, fiber loss, connectors, and transceiver readings.
- Validate link stability. Run a test long enough to catch flaps or errors.
- Check interface counters. Look for CRC errors, drops, resets, and speed mismatch.
- Run packet tests. Measure latency, loss, jitter, and throughput.
- Analyze applications. Review DNS, TCP, TLS, server response, and user experience.
This order reduces noise. It also stops teams from chasing complex theories while a simple physical fault sits in plain sight.
Image not found in postmeta
Common Mistakes to Avoid
- Trusting link up status too much. A link can be up and still perform badly.
- Ignoring dirty connectors. Cleaning is cheap. Outages are not.
- Running only short tests. Some errors appear after temperature shifts or traffic bursts.
- Mixing transceiver types without checking specs. Compatibility matters.
- Assuming packet loss is always congestion. Physical errors can look similar.
Final Recommendation
Use LOTX testing as the foundation and network diagnostic tools as the investigation layer above it. LOTX proves that the signal path is fit for service. Network tools prove that the service itself performs as expected.
For new circuits, upgrades, and unstable links, start with LOTX. For routing, application, latency, DNS, and congestion issues, use network diagnostics. The best teams use both and keep the results in the same ticket record. That creates cleaner handoffs, faster escalations, and fewer repeat incidents.